
OLS tells you how the average outcome moves with a regressor. Quantile regression tells you how the whole distribution moves: the bottom, the middle and the top, each with its own slope. If you are taking applied econometrics at the University of Chicago, Northwestern, Loyola, DePaul or UIC, it may get a single week of the course, and the same handful of misreadings appear on almost every problem set. A Chicago econometrics tutor would teach it the way this page does: one small dataset, solved exactly, and then five mistakes taken apart one at a time.
Twenty-five households and a fan-shaped cloud
Here is the dataset everything below uses. Twenty-five households report monthly income x, in thousands of USD, and monthly food spending y, in hundreds of USD. There are five households at each income from 2 to 6. At an income of 2 they spend 3.2, 3.6, 4.0, 4.4 and 5.6. At an income of 6 they spend 5.6, 6.8, 8.0, 9.2 and 12.8.
Two features matter. The spread widens with income, because richer households have more room to choose. And at every income one household spends far more than the other four, so the distribution has a long right tail. Figure 1 shows the cloud with four fitted lines.
OLS gives a slope of 1.08: an extra thousand USD of income goes with 108 USD more food spending, on average. The quantile lines say more. At the 0.25 quantile the slope is 0.8; at the median, 1.0; at the 0.75 quantile, 1.2. All three lines start from the same intercept, 2, and fan apart. Each was solved exactly, by checking every line through two data points and keeping the one with the smallest objective. Each mistake below is a way of misreading this picture.
“To study the big spenders, keep only the big spenders”
The tempting shortcut is to cut the sample. Keep the households spending 700 USD a month or more, run OLS on them, and call the slope “the effect at the top”. Eight households pass the cut. Their OLS slope is 0.75.
That is lower than the 0.25 quantile slope, let alone the 0.75 one. The cut selects on the outcome. At incomes of 3 and 4 only the one extravagant household clears 700 USD (at 2, none does), while at 5 and 6 three households clear it, including the typical one. So the retained low-income points sit unusually high and the retained high-income points sit closer to typical, and the line flattens. This is truncation bias, and it is the same reason you cannot study the returns to schooling using only people with high wages.
Quantile regression never discards a household. It keeps all 25 and changes how residuals are weighted. That is the next mistake’s subject.
“Quantile regression is least squares with extra weights”
It is not least squares at all. The τ-th quantile minimises the check function (sometimes called pinball loss):
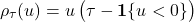
A positive residual costs τ per unit; a negative one costs 1 − τ. For τ = 0.5 both cost one half, which is least absolute deviations, and the minimiser is the median. For τ = 0.75, points above the line are three times as expensive as points below it, so the line rises until no more than a quarter of the points sit above it and no more than three-quarters below.
Why the quantile? Choose q to minimise the expected check loss. Differentiate under the expectation, splitting at q:
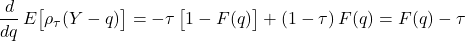
Set it to zero and you get F(q) = τ. The minimiser is the τ-th quantile, by definition. Check it on the five households at an income of 2 with τ = 0.75. The total check loss at q = 4.0 is 1.8; at q = 4.4 it falls to 1.5; at q = 5.6 it is back up to 1.8. The minimum is 4.4, the fourth of five values, which is the sample 0.75 quantile.
Regression replaces the constant q with a line:
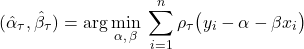
There is no OLS-style formula: the objective is piecewise linear, not smooth. It is a linear programme, and at least one optimal line always passes through at least as many data points as there are coefficients (two here; in this dataset each optimal line passes through five). That is why checking every line through a pair of points finds the exact solution. Koenker and Bassett (1978, Econometrica) introduced the estimator in this form.
“If the slopes differ, the model is broken”
Students who have just learned heteroskedasticity as a nuisance tend to read fanning quantile lines as a warning. Read them as the finding. Suppose the outcome follows a location-scale model, where the regressor shifts both the centre and the spread:
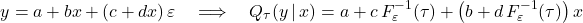
This needs ε independent of x and a positive scale, c + dx > 0. The slope at quantile τ is then b + d times the τ-quantile of the error. If d = 0, the errors are homoskedastic, every quantile line is parallel and quantile regression adds nothing to OLS about the slope. If d > 0, the spread grows with x and the lines fan out, exactly as in Figure 1.
The households were built this way: y = 2 + x + 0.2xε, where ε takes the values −2, −1, 0, 1 and 4. The 0.25, 0.5 and 0.75 quantiles of ε are −1, 0 and 1, which gives slopes of 0.8, 1.0 and 1.2. The mean of ε is 0.4, not zero, because of the long right tail. So the OLS slope is 1 + 0.2 × 0.4 = 1.08, above the median slope. The mean and the median disagree because the distribution is skewed, and that disagreement is information about the households, not an error in either estimator.
“The 0.75 coefficient is the effect on the households at the 75th percentile”
This is the most common misreading, and it shows up in published work as well as problem sets. The coefficient 1.2 says that the 0.75 quantile of the conditional distribution of food spending rises by 120 USD when income rises by a thousand. It is a statement about distributions, compared across incomes.
It is not a statement about any particular household. To say that a household at the 75th percentile at an income of 4 would still be at the 75th percentile at an income of 5, and so would spend 120 USD more, you need rank invariance: the income change must not reshuffle households within the distribution. Nothing in the data can confirm that, because you never see the same household at two incomes. Write “the upper quartile of the spending distribution rises by 120 USD”, not “high spenders increase their spending by 120 USD”, unless you are prepared to defend the assumption.
“Logs, means and medians can be swapped freely”
Quantiles survive any increasing transformation. If h is increasing, the median of h(y) is h of the median of y, and the same holds at every quantile. Means do not behave this way, because of Jensen’s inequality.
Take the five households at an income of 2 again. Their mean spending is 4.16, whose log is 1.4255. The mean of their logged spending is 1.4070, smaller. Their median is 4.0, and the median of the logs is ln 4 exactly. So a median regression of log spending can be back-transformed by exponentiating the fitted line, with no correction. A mean regression of log spending cannot: exponentiating its fitted values gives a geometric mean, which sits below the arithmetic mean, unless you add a retransformation correction. In wage regressions, where the outcome is almost always in logs, this is a real advantage of the median.
Where the uncertainty is
Inference changes too. The variance of a sample quantile is approximately τ(1 − τ) / [n f(qτ)2], where f is the density at the quantile. Where data are sparse, in the tails, f is small and the estimate is noisy. So for bell-shaped or right-skewed outcomes like these, the 0.95 quantile line is usually much less precise than the median line, even with the same sample. Some packages’ default standard errors also assume the error density is the same at every value of x, which a fanning cloud violates. Ask for a robust (sandwich) or bootstrap standard error instead, and read the result with the logic of any other hypothesis test.
Exercises with answers
Exercise 1. Seven commuters report journey times of 12, 15, 18, 20, 25, 31 and 47 minutes. Find the median and the 0.75 quantile by minimising the check loss, and compare the median with the mean.
Answer. For τ = 0.5 the loss is minimised at the fourth value, 20 minutes. For τ = 0.75 it needs at least three-quarters of the values at or below q: 7 × 0.75 = 5.25, so the sixth value, 31 minutes. (Software defaults that interpolate between values would report 28.) The mean is 168/7 = 24, above the median because of the 47-minute commute. As with the households, a right tail pulls the mean up and leaves the median alone.
Exercise 2. Earnings follow y = 3 + 2x + (1 + 0.5x)ε, for x ≥ 0, with ε standard normal and independent of x. Find the slope of the 0.1, 0.5 and 0.9 regression quantiles and the intercept of the 0.9 one. What does OLS estimate?
Answer. The slope at quantile τ is 2 + 0.5zτ. With z0.9 ≈ 1.2816, the slopes are about 1.36, 2 and 2.64. The 0.9 intercept is 3 + 1 × 1.2816 ≈ 4.28. Because ε has mean zero, OLS estimates the mean slope, 2, which here equals the median slope because the normal is symmetric.
Exercise 3. A median regression of log hourly wages on years of schooling gives log w = 1.2 + 0.08 s. By how much does one more year of schooling raise the median wage, and what is the predicted median wage for someone with 16 years?
Answer. Because quantiles are equivariant to the log, the median wage rises by a factor of e0.08, an increase of about 8.33%. The predicted median wage at 16 years is e1.2 + 1.28 = e2.48 ≈ 11.94 USD an hour. Neither statement would carry over to the mean wage from a mean regression of log wages without further assumptions.
A quantile regression tutor for University of Chicago and Northwestern coursework
Quantile regression usually arrives in a second applied course, after OLS and its assumptions, and it is often taught in Stata or R with little time on the theory. If you are working through University of Chicago econometrics problem sets, or the equivalent at Northwestern, Loyola, DePaul or UIC, a PhD tutor can go through the estimation, the interpretation and the code with you, one assignment at a time. Book a session before your next one is due.
One-on-one with a Chicago econometrics tutor
Tell us your course and the assignment, and you will be matched with a PhD tutor in econometrics for online sessions at times that suit you. Most students bring the problem set they are stuck on. Message us from the WhatsApp button at the top of the page to arrange the first session.
