
One region adopts a policy. Twelve comparable regions do not. You have ten years of data before the change and six after, and your supervisor wants an estimate of what the policy did, with inference, by Friday. There is no control region that tracks the treated one, so difference-in-differences with a hand-picked comparison is a choice you cannot defend. This is the problem synthetic control was built for, and if you are taking applied econometrics or a causal-inference field course at Harvard or MIT, or the graduate metrics sequence at Boston University, Boston College, Tufts or Northeastern, it is the method you will be asked to implement rather than describe. This synthetic control lesson from a Boston econometrics tutor states the estimator in full, solves one example exactly, from the weights to the permutation p-value, and spends as long on when the method fails as on when it works. Sessions are one-on-one, on your own data if you have it.
The data, and why a single control will not do
Thirteen regions, numbered 0 to 12, report an outcome index every year for sixteen years. Region 0 adopts the policy at the start of year 11. Its index rises from 51.6 in year 1 to 71.1 in year 10, then stalls: 70.6, 70.9, 72.2, 73.2, 76.2, 78.4. Something changed in year 11. But the twelve untreated regions grow at different rates, have different cyclical swings and start from different levels. The one with the closest level in year 10 has the wrong growth rate, the one with the right growth rate has the wrong level, and the plain average of all twelve mixes growth rates and cycles that match nothing in particular. The parallel-trends assumption that difference-in-differences needs holds for no single comparison, and nothing in the data says which one to use.
Synthetic control replaces the choice with an estimate: a weighted average of all twelve, with the weights chosen so that the average reproduces the treated region’s pre-policy history. A convex combination of untreated regions that behaved like the treated one for ten years before the policy is a credible stand-in for how it would have behaved afterwards.
The estimator, stated in full
Abadie and Gardeazabal (2003) introduced the method and Abadie, Diamond and Hainmueller (2010) gave it its inferential framework and its standard notation. There are J + 1 units observed for T periods. Unit 1 (our region 0) is treated from period T0 + 1; units 2 to J + 1 are the donor pool. Write Yit(0) for the outcome unit i would have without treatment and Yit(1) with it. The quantity of interest is the treated unit’s effect in each post-period:
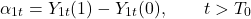
The first term is observed. The second is the counterfactual, and the synthetic control estimates it as a weighted average of donors:
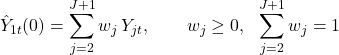
The two constraints are the method. Non-negative weights that sum to one make the synthetic unit an interpolation of the donors, never an extrapolation beyond them. That keeps the weights interpretable and stops the fit being manufactured by giving one donor a weight of 3 and another a weight of −2.
The weights are chosen before the treatment date. Let X1 be a vector of k pre-treatment characteristics of the treated unit (covariates, pre-period outcomes, or both) and X0 the k × J matrix of the same characteristics for the donors. With a k × k positive semidefinite matrix V, in practice diagonal with non-negative entries, that says how much each characteristic matters, the weights solve
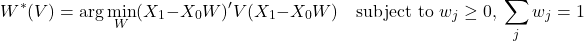
and V itself is usually chosen so that the synthetic unit fits the treated unit’s pre-period outcome path as closely as possible: an outer minimisation over V around the inner one over W. The justification is a factor model. If untreated outcomes are driven by common factors with unit-specific loadings, a synthetic unit that matches the treated unit’s pre-period history for long enough has, with high probability, also matched its unobserved loadings. The 2010 paper bounds the estimator’s bias for a synthetic unit that fits the pre-period closely, and the bound falls as the number of pre-periods grows relative to the scale of the transitory shocks. That is why a long, close pre-period fit is the first thing a referee asks about.
The example below takes the simplest case: X is the full vector of ten pre-period outcomes and V the identity, so the weights minimise the sum of squared pre-period discrepancies. One caution: with all pre-period outcomes as characteristics, the outer optimisation over V puts zero weight on any other covariates in X, whether or not they matter for the counterfactual, so they drop out without anyone deciding they should. Outcome history alone, or a few lags plus covariates, is a modelling choice to make and state.
Solving for the weights exactly
With V fixed, the inner problem is least squares on the simplex: minimise ||y1 − Y0W||2 over non-negative weights that sum to one, where y1 stacks the treated unit’s ten pre-period outcomes and Y0 is the 10 × 12 matrix of donor outcomes. Software solves it numerically; for twelve donors you can solve it exactly, which is worth doing once to see what the software finds.
The objective is convex and the constraint set a simplex, so the solution is characterised by its Karush–Kuhn–Tucker conditions: for every donor with positive weight the gradient of the objective equals a common multiplier, and for every donor with zero weight it is at least that multiplier. Equivalently, guess which donors have positive weight, solve the equality-constrained least-squares problem on that set, and accept the guess if the solved weights are all non-negative and no excluded donor would lower the objective by entering. There are 212 − 1 candidate sets; checking them takes a fraction of a second, and for these data one passes.
| Donor | 1 | 2 | 3 | 4 | 5 | 6 | 7 | 8 | 9 | 10 | 11 | 12 |
|---|---|---|---|---|---|---|---|---|---|---|---|---|
| Weight | 0 | 0 | 0.393 | 0 | 0 | 0 | 0.130 | 0 | 0.323 | 0 | 0 | 0.154 |
Four donors carry weight and eight carry none. Sparse weights are common: the solution is the projection of the treated unit’s ten-year path onto the donors’ convex hull, and when the path lies outside the hull, as here, the projection lands on a face of it and only the donors spanning that face get weight. (Inside the hull the fit would be exact and, with twelve donors and ten periods, the weights not even unique.) The pre-period root mean squared prediction error, RMSPE, is 0.29 index points on an outcome that moves about two points a year. Moving one percent of the weight from any donor to any other raises the discrepancy; that is what optimality means, and it is checked.
A detail that matters later: these data were generated, as a clean seeded example, so the truth is known. Region 0’s untreated outcome mixes the factor loadings of donors 3, 7 and 9 in the proportions 0.5, 0.3 and 0.2, plus noise. The solver found those three donors and added donor 12 to absorb noise. The proportions are only loosely right (donor 9 outweighs donor 7, the reverse of the truth), but the trend loading they imply, 1.03 against a true 1.04, is almost exact, and the loadings are what the counterfactual needs.
The counterfactual, year by year
With the weights fixed, the synthetic region’s outcome in every year, before and after the policy, is the weighted average of the four donors’ outcomes in that year.
| Year | Treated region | Synthetic region | Gap |
|---|---|---|---|
| 1 | 51.6 | 52.1 | −0.5 |
| 2 | 55.0 | 54.8 | 0.2 |
| 3 | 55.6 | 56.0 | −0.4 |
| 4 | 57.7 | 57.7 | 0.0 |
| 5 | 59.0 | 59.2 | −0.2 |
| 6 | 61.4 | 61.7 | −0.3 |
| 7 | 64.2 | 64.3 | −0.1 |
| 8 | 66.7 | 66.7 | 0.0 |
| 9 | 68.5 | 68.6 | −0.1 |
| 10 | 71.1 | 70.6 | 0.5 |
| 11 | 70.6 | 72.2 | −1.6 |
| 12 | 70.9 | 74.7 | −3.8 |
| 13 | 72.2 | 76.0 | −3.8 |
| 14 | 73.2 | 78.6 | −5.4 |
| 15 | 76.2 | 81.0 | −4.8 |
| 16 | 78.4 | 82.5 | −4.1 |
The gaps in the first ten rows are the fit. The gaps in the last six are the estimates α̂1t: the policy lowered the index by 1.6 in its first year, by about 3.8 in each of the next two, and by between 4 and 5.5 after that. Their average, −3.91 from the unrounded gaps, is the single number most papers report. The true effects were −2, −3.5, −4.5, −5, −5 and −5, averaging −4.17, so the estimate is 0.26 too small in magnitude, within the noise of a pre-period RMSPE of 0.29 and six post-period draws.
Two things the table does not give you: a standard error, because there is one treated unit and the weights were chosen to fit it, and any sense of whether a gap of 3.9 is remarkable, because you have not yet seen how large a gap the method produces when there is no policy at all.
Inference by permutation
Abadie, Diamond and Hainmueller’s answer to both is to run the estimator where it should find nothing. Take each donor in turn, pretend it was the one treated in year 11, build its synthetic control from the other eleven, and record its gap path. These are placebos in space. If the treated region’s post-period gap is unusual relative to the twelve placebo gaps, the policy did something; if several placebos show gaps as large, the method cannot tell. The comparison must account for fit, because a placebo whose synthetic control never matched it has large gaps everywhere, so the statistic is the ratio of post-period RMSPE to pre-period RMSPE: how much worse the fit became after year 10.
| Unit | Pre-period RMSPE | Post-period RMSPE | Ratio |
|---|---|---|---|
| Treated region (0) | 0.29 | 4.09 | 14.20 |
| Donor 1 | 3.23 | 5.60 | 1.73 |
| Donor 2 | 1.65 | 3.43 | 2.08 |
| Donor 3 | 0.57 | 0.59 | 1.04 |
| Donor 4 | 0.50 | 1.01 | 2.02 |
| Donor 5 | 0.49 | 0.87 | 1.79 |
| Donor 6 | 0.41 | 0.88 | 2.13 |
| Donor 7 | 1.23 | 1.39 | 1.13 |
| Donor 8 | 0.43 | 0.58 | 1.34 |
| Donor 9 | 0.42 | 0.82 | 1.97 |
| Donor 10 | 1.18 | 3.45 | 2.93 |
| Donor 11 | 1.63 | 3.03 | 1.86 |
| Donor 12 | 0.44 | 0.73 | 1.66 |
The treated region’s ratio, 14.2, is nearly five times the largest placebo ratio, 2.93. (Abadie, Diamond and Hainmueller use the ratio of mean squared errors; RMSPE ratios give the same order.) Among the thirteen units it ranks first, so the permutation p-value is 1/13 = 0.077. Read that number carefully. It is the probability of a ratio this extreme if the policy had been assigned to one of the thirteen units at random, a reading that needs assignment to be as good as random across units; otherwise it describes how unusual the gap is relative to the placebo gaps. And with twelve donors it is the smallest p-value this test can produce: no in-space permutation test with twelve donors can report significance at the 5 percent level, however large the effect. Newer methods, permuting over time periods (Chernozhukov, Wüthrich and Zhu 2021) or building prediction intervals (Cattaneo, Feng and Titiunik 2021), get their resolution from the number of periods instead.
Placebos that never fitted their own pre-period need handling. In their gap-path figures, Abadie, Diamond and Hainmueller progressively drop donors whose pre-period mean squared error exceeds twenty, five and then two times the treated unit’s. Here the treated unit’s fit is so tight that the twenty-times cut keeps nine placebos, the five-times cut keeps seven (donors 1, 2, 7, 10 and 11 go) and the two-times cut keeps none. That is why the ratio statistic exists: it normalises each placebo by its own fit and needs no screening, and the 2010 paper computes its ratio p-value over every placebo. Restrict the ratio test to the seven placebos within five times and the treated region still ranks first with p = 1/8 = 0.125; screening can only raise the floor on the p-value by shrinking the count. Report the unscreened ratio p-value, and if you also screen, say why.
Two more checks belong in any write-up. The in-time placebo moves the treatment date to a year when nothing happened: fit the weights on years 1 to 5 only and look at years 6 to 10. The same four donors are chosen, with weights 0.456, 0.145, 0.257 and 0.142, and the mean gap over the fake post-period is 0.26, against −3.91 for the real one. The leave-one-out check drops each positive-weight donor in turn: without donor 3 the effect is −3.73, without donor 7 it is −4.04, without donor 9 it is −3.74 and without donor 12 it is −3.96. An estimate that collapsed when one donor left would be an estimate of that donor, not of the policy.
When the method fails
Everything above rests on the pre-period fit, and the fit can fail for reasons no computation repairs.
The treated unit is outside the convex hull. If the treated region is richer, larger or faster-growing than every donor, no non-negative weights summing to one can reproduce it. The fit lands on the boundary of the hull, on a face with a few donors or, as in Problem 3, on a single vertex, and the pre-period gap is visibly non-zero. Negative weights would fit, and turn the method into a regression that extrapolates. The 2010 paper’s advice is to choose the donor pool so that the treated unit is inside the hull, the 2021 survey adds rescaling the outcome, and if neither works, say so.
Too few pre-periods relative to the donors. With three pre-periods and twelve donors the simplex can fit anything, including noise, and a good fit proves nothing. The bias bound shrinks with the length of the pre-period relative to the transitory variance; report both.
Contaminated donors. The method assumes no interference: a donor itself affected by the policy, through spillovers, migration or a parallel reform, is not a control. Abadie, Diamond and Hainmueller dropped the states with similar programmes or large tax rises of their own. The donor pool is an argument, not a dataset.
Anticipation. If the treated region began responding before the official date, the weights are fitted to a contaminated history. Move T0 back and check the in-time placebo.
Small effects on noisy outcomes. A single-unit method has nowhere to hide a one-off shock in year 12, and an effect that is small relative to the outcome’s year-to-year volatility will not separate from the placebo gaps however good the fit. The placebo distribution is the only protection, and it is weak when donors are few.
In the spirit of Abadie’s 2021 survey, which rests the case for the method on transparency, no extrapolation and protection against specification search: synthetic control is a transparent way of choosing a comparison, not of creating one where none exists. The fixed-effects panel estimator assumes the comparison in its error structure; synthetic control makes you show it.
Where problem-set answers go wrong
The most common failure is matching on the post-period. A student who includes years 11 to 16 in the fit, or searches over V and the predictor set until the gap looks dramatic, has estimated nothing: the weights were chosen to produce the answer. The pre-period is the only information the weights may touch, and the predictor set should be fixed and reported before anyone looks at the gap.
The next is reporting a t-statistic from a regression of the gap on a post-period dummy. Those residuals are not independent draws from anything; they are the fitting errors of a procedure that chose its own comparison. The in-space permutation distribution is the baseline inference and the time-permutation and prediction-interval methods above are its complements; a naive t-statistic is neither.
Third, reading weights as importance. A donor with weight 0.39 is not “the region most similar to the treated one”; it is the donor whose outcome history, combined with three others, reproduces the treated history, and a different donor pool gives different weights. Discuss them as a diagnostic, not as findings.
Fourth, silence about the hull: if the treated unit’s outcome in year 10 is above every donor’s, say so in the first paragraph, because it decides whether the method applies. And fifth, the 5 percent reflex: with twelve donors, write 1/13 and explain what it means. A marker who sees “p < 0.05" from a 13-unit permutation test knows the student did not count. For a design that does deliver conventional standard errors, compare regression discontinuity.
Three problems, one of them hard
Problem 1. Three donor regions have pre-period outcomes (10, 12), (20, 18) and (14, 22) over two years; the treated region’s are (15, 17). In the post-period the donors record 13, 21 and 25 and the treated region 16. Find the synthetic-control weights and the estimated effect.
Answer. With two pre-periods and the sum-to-one constraint there are three equations in three unknowns: w1 + w2 + w3 = 1, 10w1 + 20w2 + 14w3 = 15, 12w1 + 18w2 + 22w3 = 17. Substituting the first into the other two gives 10w2 + 4w3 = 5 and 6w2 + 10w3 = 5, so w3 = 2/7.6 = 0.263, w2 = 0.395 and w1 = 0.342. All three are positive, so the treated region lies inside the donors’ hull and the exact fit is also the constrained optimum. The synthetic post-period outcome is 0.342 × 13 + 0.395 × 21 + 0.263 × 25 = 19.32, and the estimated effect is 16 − 19.32 = −3.32. Say in your answer that two pre-periods prove little.
Problem 2. A study has eight donors. Their post-to-pre RMSPE ratios are 1.4, 0.8, 2.6, 1.1, 0.6, 3.9, 1.7 and 0.9, and their pre-period RMSPEs are 0.9, 1.1, 0.8, 1.2, 1.0, 3.3, 0.7 and 1.0; the treated unit’s pre-period RMSPE is 1.0. (a) The treated unit’s ratio is 5.2: what is the permutation p-value? (b) Suppose instead it were 3.0. (c) Apply a screen that drops placebos whose pre-period MSPE is more than twice the treated unit’s, and redo (b) among the remaining units. What is the smallest p-value this test could report in each case?
Answer. (a) Nine units; 5.2 ranks first; p = 1/9 = 0.111. (b) 3.0 ranks second behind 3.9, so p = 2/9 = 0.222. (c) Twice the treated unit’s MSPE is 2.0, an RMSPE of about 1.41, so the screen drops only the donor with pre-period RMSPE 3.3, whose ratio was the 3.9. Among the remaining eight units 3.0 ranks first and p = 1/8 = 0.125. The smallest attainable p-value is 1/9 = 0.111 unscreened and 1/8 after the screen; neither reaches 0.05.
Problem 3 (hard). Three donors have pre-period outcomes (10, 11, 12, 13), (12, 13.5, 15, 16.5) and (9, 9, 11, 12) over four years; the treated region’s are (14, 15.5, 17, 18.5). In the post-period the donors record 14, 18 and 13 and the treated region 21. Find the synthetic-control weights and pre-period RMSPE. Then drop the non-negativity constraint, keep the sum-to-one constraint, and find the least-squares weights and fit. Finally, look at the pre-period gap of the constrained fit and decide what, if anything, the write-up can report.
Answer. The treated region exceeds every donor in every year, so it lies outside the convex hull. The constrained solution is a vertex: all weight on donor 2, the one closest from below, with weights (0, 1, 0), a pre-period RMSPE of 2.00, an implied counterfactual of 18 and an implied effect of +3. The fit failed, so those numbers are not an estimate. Dropping non-negativity gives weights (−0.03, 1.50, −0.47): a pre-period RMSPE of 0.30, a counterfactual of 20.46 and an effect of 0.54. That fit looks far better and is worse: it scales donor 2 up by half and subtracts half of donor 3, a combination of regions that does not exist, and the counterfactual inherits the extrapolation. Now look at the constrained fit’s gap: exactly 2 in all four years. A constant gap is a level difference, the one failure a parallel-trends argument repairs. Allow an intercept in the synthetic control, equivalent to running the method on demeaned outcomes, and the solution is an intercept of 2 with all weight still on donor 2: pre-period RMSPE zero, counterfactual 18 + 2 = 20, effect +1. That is the number to report, with its assumption stated: the treated region is assumed to keep tracking donor 2 at a fixed distance, which is difference-in-differences against one donor, and the constant pre-period gap is the evidence. The hard part is recognising that the raw method’s failure here is informative, not fatal.
If synthetic control is on your problem set this term, or in your second-year paper, the fastest way to get the weights, the placebo distribution and the write-up right is to build them once on your own data with a metrics tutor in Boston. One-on-one econometrics tutoring for Harvard and MIT students, and for the graduate metrics courses at Boston University, Boston College, Tufts and Northeastern, works from your code and your donor pool.
Book a Boston econometrics tutor for causal inference, from DiD to synthetic control
Send the problem set, the replication package or the draft that is stuck, and a PhD tutor in econometrics will set up online sessions around a Boston timetable, picking up from exactly where your course left you. Use the WhatsApp button at the top of this page, or book a first session through the form.
