
Add one interaction term to a wage regression and the sign of a dummy variable can reverse. It is the single most common source of confused answers in the dummy-variables chapter, and it turns up in second-year econometrics at HKU, HKUST and CUHK as reliably as it does anywhere. This page, written by a Hong Kong econometrics tutor, starts from that puzzle on a dataset small enough to check by hand and builds the theory that resolves it: what a dummy does, what an interaction does, how to test them, and the trap that catches everyone once.
Twelve workers, three regressions, one reversal
Six workers are in the private sector and six in the public sector. For each you know years of experience and hourly pay, in dollars.
| Experience (years) | 0 | 2 | 4 | 6 | 8 | 10 |
|---|---|---|---|---|---|---|
| Private-sector pay | 21 | 22 | 26 | 29 | 31 | 36 |
| Public-sector pay | 23 | 22.5 | 25 | 26.5 | 27 | 30.5 |
Let Public be 1 for a public-sector worker and 0 otherwise. Here are three regressions of pay on this data, each solved by OLS.
| (1) | (2) | (3) | |
|---|---|---|---|
| Constant | 27.5 | 21.875 | 20 |
| Public | −1.75 | −1.75 | +2 |
| Experience | 1.125 | 1.5 | |
| Public × experience | −0.75 |
Columns (1) and (2) agree that the public sector pays 1.75 less. Column (3) adds the product of the dummy and experience, and suddenly the public sector pays 2 more. Nothing about the workers changed. Which coefficient is right? All three are, once you know what question each one answers.
What a dummy does to a regression line
Start with column (2):
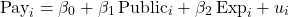
Substitute the two values of the dummy. For private workers the fitted line is β0 + β2Exp. For public workers it is (β0 + β1) + β2Exp. Same slope, different intercept. A dummy shifts the line up or down and does nothing else, so β1 is the vertical distance between two parallel lines: 21.875 + 1.125 Exp for the private sector, 20.125 + 1.125 Exp for the public.
Column (1), with no experience term, simply compares group means. The private mean is 27.5 and the public mean 25.75, so the coefficient is their difference. Adding experience left it at −1.75 because both groups have exactly the same experience profile. In real data they rarely do, and then the dummy moves when you add controls, for exactly the reason omitted variable bias describes.
Look at the slope in column (2), 1.125. It is a compromise. Here it is exactly the average of the two sectors’ own slopes, because both sectors have the same spread of experience; in general it is an average weighted by each sector’s variation in experience. Either way it is forced to be common. If the sectors reward experience differently, column (2) is misspecified, and the single number −1.75 is hiding something.
Letting the slopes differ
An interaction term multiplies the dummy by the continuous regressor:
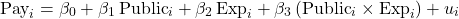
Substitute again. Private workers get β0 + β2Exp. Public workers get (β0 + β1) + (β2 + β3)Exp. Now the intercept and the slope can differ. With the estimates from column (3), the private line is 20 + 1.5 Exp and the public line is 22 + 0.75 Exp. These are exactly the lines you would get by running a separate regression for each sector. A fully interacted model is two regressions written as one. The coefficients are identical; the standard errors match only if the error variance is the same in both sectors, which the single regression (and the Chow test below) assumes.
The interaction coefficient, −0.75, is the difference in slopes. Each extra year of experience adds 1.50 an hour in the private sector and only 0.75 in the public sector.
The reversal, explained: a main effect lives at zero
In column (3), β1 = 2 is the gap between the two lines where the interacted variable equals zero. Workers with no experience at all earn 2 more in the public sector. That is a real feature of this data, a higher starting salary on a flatter scale, but it is a statement about new entrants only.
The gap at any experience level is the difference in predicted pay between the two sectors at that experience:
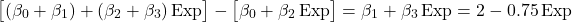
The gap shrinks by 0.75 a year. It hits zero at 2/0.75 = 8/3, about 2.7 years, and turns negative after that. At 5 years, the average experience in the sample, it is 2 − 0.75 × 5 = −1.75. That is the number columns (1) and (2) reported. There was never a contradiction. Column (3) reports the gap at zero experience; the other two report it, in effect, at the average, exactly so here because both sectors have the same average experience.
The fix that makes column (3) easy to read is centring. Replace experience with experience minus 5, its mean, and rerun. The interaction is unchanged at −0.75, but the dummy’s coefficient becomes −1.75, the gap at average experience. Nothing about the fit changes, only what the coefficient on the dummy measures. When zero is outside the data, or meaningless (a regressor like height or age), centre before you interpret.
Testing whether the sectors really differ
Two questions, two tests. First: do the slopes differ? That is a t-test on the interaction alone. Column (3) has 12 − 4 = 8 residual degrees of freedom and a residual sum of squares of 8, so the error variance estimate is 1. Each sector’s experience values have a sum of squared deviations of 70, which puts the standard error of the interaction at about 0.169. The t-statistic is −0.75/0.169 ≈ −4.44, beyond even the 1% critical value with 8 degrees of freedom, about 3.36.
Second: is the public sector different in any way, intercept or slope? That is a joint test that β1 and β3 are both zero, the Chow test (Chow 1960, Econometrica). Estimate the restricted model, one common line for everyone, and compare its residual sum of squares with the unrestricted one:
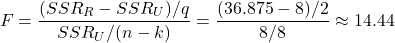
With q = 2 restrictions and 8 residual degrees of freedom, the 5% critical value of F is about 4.46, so you reject a single line for both sectors. Note what the test does not tell you: which coefficient differs. The t-tests answer that, remembering that the t-test on the dummy itself tests the gap at zero experience unless you centre.
The dummy trap and the base category
Why not include a Private dummy as well? Because Public + Private = 1 for every worker, which is exactly the constant term. The regressors are perfectly collinear, the matrix X′X cannot be inverted and OLS has no unique solution. This is the dummy variable trap. With m categories, include m − 1 dummies and a constant. The omitted category is the base, and every dummy coefficient is a difference from it.
Choosing the base changes how the coefficients read, never what the model says. Exercise 2 shows the arithmetic. Two more habits matter in practice. In a log-pay regression, a dummy coefficient b means a difference of 100(eb − 1) percent, which is close to 100b only when b is small. And when you interact two dummies, the interaction is a difference of differences, the same object that difference-in-differences estimates.
Practice questions
Question 1. In a regression of log hourly pay, a union-membership dummy has coefficient 0.12 and a part-time dummy has coefficient −0.25. Convert each into an exact percentage difference.
Answer. Union: 100(e0.12 − 1) ≈ 12.75%. Part-time: 100(e−0.25 − 1) ≈ −22.12%. The approximation 100b would give 12% and −25%; it errs more for the larger coefficient.
Question 2. With the private sector as the base, a log-pay regression gives a constant of 2.9, a public-sector dummy of 0.10 and a non-profit dummy of 0.04. Rewrite the estimates with the public sector as the base.
Answer. The public sector’s predicted log pay is 2.9 + 0.10 = 3.0, which becomes the new constant. The private sector is 0.10 below it, so its dummy is −0.10. The non-profit sector is 0.04 − 0.10 = −0.06 relative to the public sector. Every predicted value is unchanged.
Question 3. Pay = 18 + 3 Degree + 2 Urban + 1.5 (Degree × Urban), with both regressors dummies. Find the predicted pay in all four cells and the degree premium in rural and urban areas. What is the interaction coefficient measuring?
Answer. Rural without a degree: 18. Rural with a degree: 21. Urban without a degree: 20. Urban with a degree: 18 + 3 + 2 + 1.5 = 24.5. The degree premium is 3 in rural areas and 4.5 in urban ones. Their difference, 1.5, is the interaction coefficient: how much larger the degree premium is in cities.
HKU econometrics, HKUST and CUHK: working through it together
If dummy variables and interactions are on your problem set at HKU, HKUST or CUHK, a PhD tutor can take you through your own regressions one-on-one, from setting up the dummies to reading the Stata or R output and writing the interpretation that markers want. Centring is the kind of interpretation question that comes up on HKU econometrics assignments, so it is worth having ready. Book a first session before the next one is due.
Econometrics tuition in Hong Kong, built around your course
Tell us which course you are taking and what is due, and a PhD tutor in econometrics will work through it with you in one-on-one online sessions, timed for your evenings or weekends. You can book through the form or message us on WhatsApp from the top of this page.
