
Two graduates sit the same interview with the same degree on their CVs and very different abilities. The firm cannot see the difference. It can only see what each of them chose to study. If you are taking a graduate theory sequence at Harvard or MIT, or upper-level micro at Boston University, Boston College, Tufts or Northeastern, Spence’s job-market model is where signalling games stop being a definition and become algebra. This is the lesson a microeconomics tutor would give you on it: both kinds of equilibrium side by side, solved on one set of numbers, and exactly how the Cho–Kreps intuitive criterion chooses between them.
The game in four primitives
Spence’s 1973 paper in the Quarterly Journal of Economics asked how a costly action can carry information that words cannot. Signalling is the informed side’s answer to adverse selection, so if the market for lemons is hazy, revisit it first. It is also the mirror image of moral hazard and the principal–agent problem, where the hidden thing is an action rather than a type. Strip the story down and four pieces remain.
- Types. Productivity is θ ∈ {θL, θH} with θH > θL. Nature draws the high type with probability λ, strictly between 0 and 1. The worker knows their type. Nobody else does.
- The signal. Before entering the market, the worker chooses education e ≥ 0. In the pure model it adds nothing to output. It is a credential, not a skill.
- Costs. Education costs cθe, with cL > cH > 0. The coursework is cheaper for the abler worker.
- Wages. At least two firms observe e but not θ. They share a common belief μ(e), the probability that a worker with education e is high type, and bid for the worker until profit is zero.
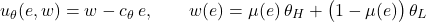
The assumption doing all the work is cL > cH. In education–wage space an indifference curve is the line w = u + cθe, so the low type’s lines are steeper. A line of one type and a line of the other cross exactly once. That is single crossing. It guarantees there are education levels the high type will pay for and the low type will not, which is the only reason a credential can mean anything.
A perfect Bayesian equilibrium (PBE) here is three objects, not one: strategies eL and eH, a wage schedule w(e), and a belief μ(e) at every education level, chosen or not. (Strategies are pure here; the hybrid equilibria mentioned later let one type randomise.) It must satisfy three conditions.
- Each type’s education maximises w(e) − cθe, taking the schedule as given.
- Each wage equals expected productivity under the belief at that education level, so firms earn zero.
- Beliefs follow Bayes’ rule wherever the equilibrium puts positive probability. Off the path, PBE leaves them free.
That last freedom is why the model has so many equilibria. It is also exactly what the refinement disciplines later. If best responses still feel shaky, rebuild them with Nash equilibrium and dominant strategies before going further.
Separating equilibria: a continuum, not a point
In a separating equilibrium the two types choose different education, so beliefs on the path are degenerate: μ(eL) = 0 and μ(eH) = 1. Write Δ = θH − θL for the productivity gap.
Start with the low type. Once identified, they earn θL. No belief can push the wage at e = 0 below θL, because expected productivity is never lower than that. So any positive eL is cost with no return, and eL = 0.
Now fix eH. Give the firms the most pessimistic off-path belief, μ(e) = 0 at every e other than eH. Pessimism makes deviations as unattractive as possible, so it supports the widest set of equilibria. The best deviation for either type is then e = 0 at wage θL, and two incentive constraints remain.

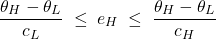
Every eH in that interval is a separating PBE. Because cL > cH, the interval is never empty. At its lower end the low type is exactly indifferent about mimicking. That point is the least-cost separating outcome, often called the Riley outcome after Riley’s 1979 Econometrica paper.
Read Figure 1 from the low type’s side first. Their indifference line through EL runs straight into the corner of the wage schedule. Set the threshold any lower and they would jump to it. Now the high type. Their line through EH meets the wage axis at 55, above the 40 they would get by copying the low type, so they strictly prefer to separate. The dashed line marks the other end of the range. Demand more than 6 units and the high type would rather be paid as a low type.
Pooling equilibria: one credential for everyone
In a pooling equilibrium both types choose the same ep. Bayes’ rule then says the credential reveals nothing, so μ(ep) = λ and the wage is the prior mean.
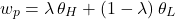
Keep the off-path belief pessimistic. The best deviation is again e = 0 at wage θL, and neither type may want it.
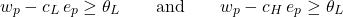
The low type’s condition is the tighter one, since their education costs more. So pooling survives at every ep from 0 up to (wp − θL)/cL. Another continuum. Note the bottom of it: a pool in which nobody studies and everyone earns the average always exists.
Separating against pooling, side by side
| Separating | Pooling | |
|---|---|---|
| Education chosen | eL = 0; eH from Δ/cL to Δ/cH | both types ep, from 0 to (wp − θL)/cL |
| Beliefs on the path | 0 or 1: the credential reveals the type | λ: the credential reveals nothing |
| Wages | θL and θH | wp for everyone |
| Who pays for education | the high type, to prove itself | both types, for no information |
| Constraint behind the key boundary | the low type’s incentive to mimic sets the least-cost end | the low type’s deviation to e = 0 sets the upper end |
| Passes the intuitive criterion | only the least-cost one | never |
Two lessons sit in that table. Both families are continua, so PBE on its own predicts almost nothing about how much education you will see. And the boundaries that matter, the least-cost end of the separating range and the only binding edge of the pooling range, are both set by the low type’s incentive. The high type’s constraint only caps how wasteful separation can get. Graders notice that second point. A common answer writes down the high type’s constraint and stops.
One labour market, both equilibria
Take graduates applying for analyst roles. Output is measured in thousands of USD a year: a low type produces 40 and a high type 70. Education e is semesters of extra quantitative coursework. Each semester costs a low type the equivalent of 10 and a high type 5, because the material comes easier to them. Six applicants in ten are high type, so λ = 0.6.
- Full information. If firms could see θ, they would pay 40 and 70 and nobody would study. Expected output is 0.6 × 70 + 0.4 × 40 = 58 per worker.
- The separating range. With Δ = 30, ICL needs eH ≥ 30/10 = 3 and ICH needs eH ≤ 30/5 = 6. Every level from 3 to 6 semesters supports a separating PBE.
- The least-cost outcome. At eH = 3 the low type earns 40 whether they copy or not, so they are indifferent. The high type keeps 70 − 5 × 3 = 55. They spend 15 on a credential that produces nothing.
- The pooling wage. If the credential reveals nothing, everyone is paid 0.6 × 70 + 0.4 × 40 = 58.
- The pooling range. The low type accepts the pool only while 58 − 10ep ≥ 40, which means ep ≤ 1.8. The high type’s own bound, (58 − 40)/5 = 3.6, never binds.
- Payoffs compared. Pooling at zero gives the low type 58 instead of 40, and the high type 58 instead of 55. Both are better off.
- Efficiency compared. Output is 58 per worker in every equilibrium, because education is unproductive. The least-cost separating outcome burns 0.6 × 15 = 9 of it on coursework, leaving 49 for workers. Pooling at zero burns nothing and leaves all 58.
Step 6 is the uncomfortable one. Keep it in mind, because the refinement below throws away the outcome both types prefer.
Cho and Kreps: which off-path beliefs are reasonable
PBE lets a firm believe anything at an education level nobody chooses. The intuitive criterion of Cho and Kreps (1987, Quarterly Journal of Economics) asks one question of each unused level e′: could this type possibly gain by choosing it? Call e′ equilibrium-dominated for a type if, even at the best wage any belief could produce, θH, that type does worse than in the equilibrium.
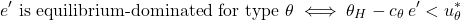
Here the starred term is the type’s equilibrium payoff. The test then runs in two steps. First, the belief at e′ must put zero weight on every type for which e′ is equilibrium-dominated. Second, if some type would earn strictly more than its equilibrium payoff under every wage those restricted beliefs allow, the equilibrium fails. If e′ is dominated for every type, the test places no restriction there at all.
With two types this becomes mechanical. If e′ is dominated for the low type but not for the high type, the belief must be μ(e′) = 1 and the wage θH. Then you only ask whether the high type gains.
Pooling fails. Take the pool at zero, with wage 58. The low type’s payoff is 58, so a deviation e′ is dominated for them once 70 − 10e′ < 58, that is e′ > 1.2. The high type gains from being read as high whenever 70 − 5e′ > 58, that is e′ < 2.4. Any e′ in D = (1.2, 2.4) breaks the pool. At e′ = 1.5, the low type’s best case is 70 − 15 = 55, below 58, while the high type would collect 70 − 7.5 = 62.5, above 58. So a reasonable belief at one and a half semesters is μ = 1, the wage there would be 70, and the high type would leave the pool for it. No belief that survives the test can hold the pool together.
The argument works at any pooling level. D runs from ep + (θH − wp)/cL to ep + (θH − wp)/cH. It is non-empty whenever wp < θH, which holds for any λ < 1. Single crossing is the whole reason.
Wasteful separation fails too. Suppose the high type separates at eH = 5, keeping 70 − 25 = 45. Try e′ = 4. The low type’s best case there is 70 − 40 = 30, below their 40, so the level is dominated for them. The high type, paid 70, would keep 70 − 20 = 50, above 45. The equilibrium fails, and the same is true at every e′ strictly between 3 and 5.
The least-cost outcome survives. At eH = 3, any e′ below 3 is not dominated for the low type: paid 70 there, they would beat their 40. So beliefs at those levels are unrestricted, and pessimistic ones still support the equilibrium. Any e′ above 3 cannot tempt the high type, who already earns 70 for less coursework. Nothing breaks it. In the two-type model it is the only PBE outcome that passes, hybrid equilibria in which one type randomises included.
With three or more types the intuitive criterion no longer delivers a unique prediction. The stronger D1 criterion, also defined by Cho and Kreps and close to the universal divinity of Banks and Sobel (1987, Econometrica), restores the least-cost separating outcome; Cho and Sobel (1990, Journal of Economic Theory) prove the general version. Problem 3 below asks you to compute that outcome with three types.
The refinement can choose the outcome everyone likes less
Go back to step 6. With λ = 0.6, both types prefer pooling at zero to the least-cost separating outcome, yet the intuitive criterion kills the pool. Where is the line? The low type always prefers the pool, since wp > θL. The high type prefers it exactly when
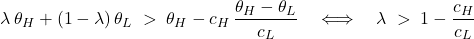
Here the threshold is 1 − 5/10 = 0.5. Above it, the refined equilibrium is Pareto-dominated by pooling at zero. That is the standard critique, and it is worth stating precisely. The criterion asks whether a deviation is credible relative to the equilibrium under test. It never asks whether that equilibrium is worth having. The undefeated equilibrium of Mailath, Okuno-Fujiwara and Postlewaite (1993, Journal of Economic Theory) builds that comparison in, and can select the pool. On a problem set, though, the expected answer is the least-cost separating outcome, followed by one sentence noting that it can be Pareto-dominated when high types are common.
The mistakes that cost marks
The commonest slip is a separating “equilibrium” with no beliefs. A PBE without off-path beliefs is incomplete, and a grader will treat it as unproven. State μ(e) everywhere. A threshold rule, μ(e) = 1 for e ≥ 3 and 0 otherwise, is enough.
Close behind is giving the low type positive education in a separating equilibrium. Once they are identified as low, every unit of education is pure cost. If your algebra produces eL > 0, a constraint is pointing the wrong way.
Then there is binding the wrong constraint. The least-cost level comes from the low type’s temptation to mimic, Δ/cL, not from the high type’s willingness to pay, Δ/cH. Swap them and you report the most wasteful separating equilibrium as the refined one.
Many answers also apply the intuitive criterion in one step instead of two. “The high type would deviate” proves nothing by itself. You must first show the deviation is equilibrium-dominated for the low type, because that is what licenses the belief μ(e′) = 1. Markers look for that sentence.
Finally, check the wage-setting assumption. The zero-profit schedule w(e) = E[θ | e] needs at least two firms competing. A single employer facing a fixed outside option pays that option whatever e is, so nobody has a reason to study and the signal collapses. Keep education unproductive unless the question says otherwise. Let it raise output and the welfare comparison in step 7 no longer holds.
Three problems to work
Problem 1 (warm-up). Let θL = 30, θH = 54, cL = 12, cH = 4 and λ = 0.25. Find the separating range, the least-cost level and the high type’s payoff there. Then find the pooling wage and the pooling range. Does the high type prefer the pool at zero?
Answer. The separating range runs from 24/12 = 2 to 24/4 = 6. At the least-cost level eH = 2 the high type keeps 54 − 8 = 46. The pooling wage is 0.25 × 54 + 0.75 × 30 = 36, sustainable for ep from 0 to 0.5. The high type prefers separating, 46 against 36. The pool at zero would Pareto-dominate only if λ exceeded 1 − 4/12 = 2/3.
Problem 2 (the refinement). Use the analyst-market numbers. Show that pooling at ep = 1 is a PBE under pessimistic off-path beliefs. Find its deviation set D and check one point inside it.
Answer. In the pool the low type keeps 58 − 10 = 48 and the high type 58 − 5 = 53. Both beat the 40 on offer at e = 0, so neither deviates there. D = (1 + 12/10, 1 + 12/5) = (2.2, 3.4). At e′ = 3 the low type’s best case is 70 − 30 = 40, below 48, while the high type would keep 70 − 15 = 55, above 53. The pool fails.
Problem 3 (hard: three types). Productivities are 40, 70 and 100, and each unit of education costs the three types 10, 6 and 4. Find the least-cost separating education levels and each type’s payoff. Explain why the only constraints that bind are those stopping each type from copying the next type up, and check two constraints that do not bind.
Answer. Type 1 chooses 0. Type 2 must leave type 1 indifferent, so e2 = 30/10 = 3. Type 3 must leave type 2 indifferent, so e3 = 3 + 30/6 = 8. Payoffs are 40, 70 − 18 = 52 and 100 − 32 = 68. Single crossing chains the constraints. Type 2 is indifferent between its own bundle and type 3’s; type 1, with steeper indifference lines, therefore strictly prefers type 2’s bundle to type 3’s, and it already weakly prefers its own to type 2’s. Checking two that do not bind: type 1 copying type 3 keeps 100 − 80 = 20, far below 40, and type 3 copying type 2 keeps 70 − 12 = 58, below 68. Every constraint that stops a higher type from copying a lower one is slack, because extra coursework costs the higher type less, so the wage premium it buys is worth more to them.
Working with a Boston microeconomics tutor
Signalling is usually the first place a theory sequence makes you write down beliefs off the equilibrium path, and the move from PBE to refinements is where marks quietly disappear. If your Harvard and MIT microeconomics problem sets, or those at another Boston school, ask you to defend a refinement in words, a one-on-one session with a PhD tutor can go through your own assignment line by line: the beliefs you wrote, the constraint you bound, the deviation you tested. See how sessions are arranged.
Questions students ask about signalling
How is signalling different from screening? In signalling the informed side moves first: the worker picks education, then firms respond. In screening the uninformed side moves first, offering a menu of contracts that makes types sort themselves, as in Rothschild and Stiglitz’s 1976 insurance model. The information problem is the same. The timing differs, and so, often, do the equilibria.
Does the model say education is useless? No. It says education can raise wages even if it raises nothing else, so a positive return to schooling does not by itself prove that schooling builds skill. Empirical work tries to separate the two channels. The theory only shows how easily they are confused.
Why not use subgame perfection instead of PBE? The firms move at an information set containing both types, so no proper subgame starts after the worker’s choice. Subgame perfection then adds nothing beyond Nash equilibrium. You need beliefs at that information set, and PBE is what supplies them.
Signalling, refinements and the rest of the Harvard and MIT theory sequence, one-on-one
Send the problem set that is stuck, or the lecture that did not land, and you will be matched with a PhD tutor. If you have been looking for an economics tutor in Boston who can handle graduate theory, sessions run online and fit around your term. Start with the short booking form, or use the WhatsApp button at the top of this page.
